A familiar office scene: someone asks an internal AI assistant about the company’s travel policy. The answer appears in seconds, written with the calm confidence these systems have even when they’re making things up.
The employee reads it, nods, and nearly books a hotel outside the allowed limit.
The AI found an old policy document.
That small incident explains both why RAG is useful and why people oversell it. RAG can make an AI far more useful inside a company. It can also deliver outdated nonsense in excellent English. The difference often has less to do with the model’s intelligence and more to do with whether the system found the right page before answering.
The clever part is mostly search
RAG stands for retrieval-augmented generation, which sounds like something designed to make a simple idea difficult to discuss.
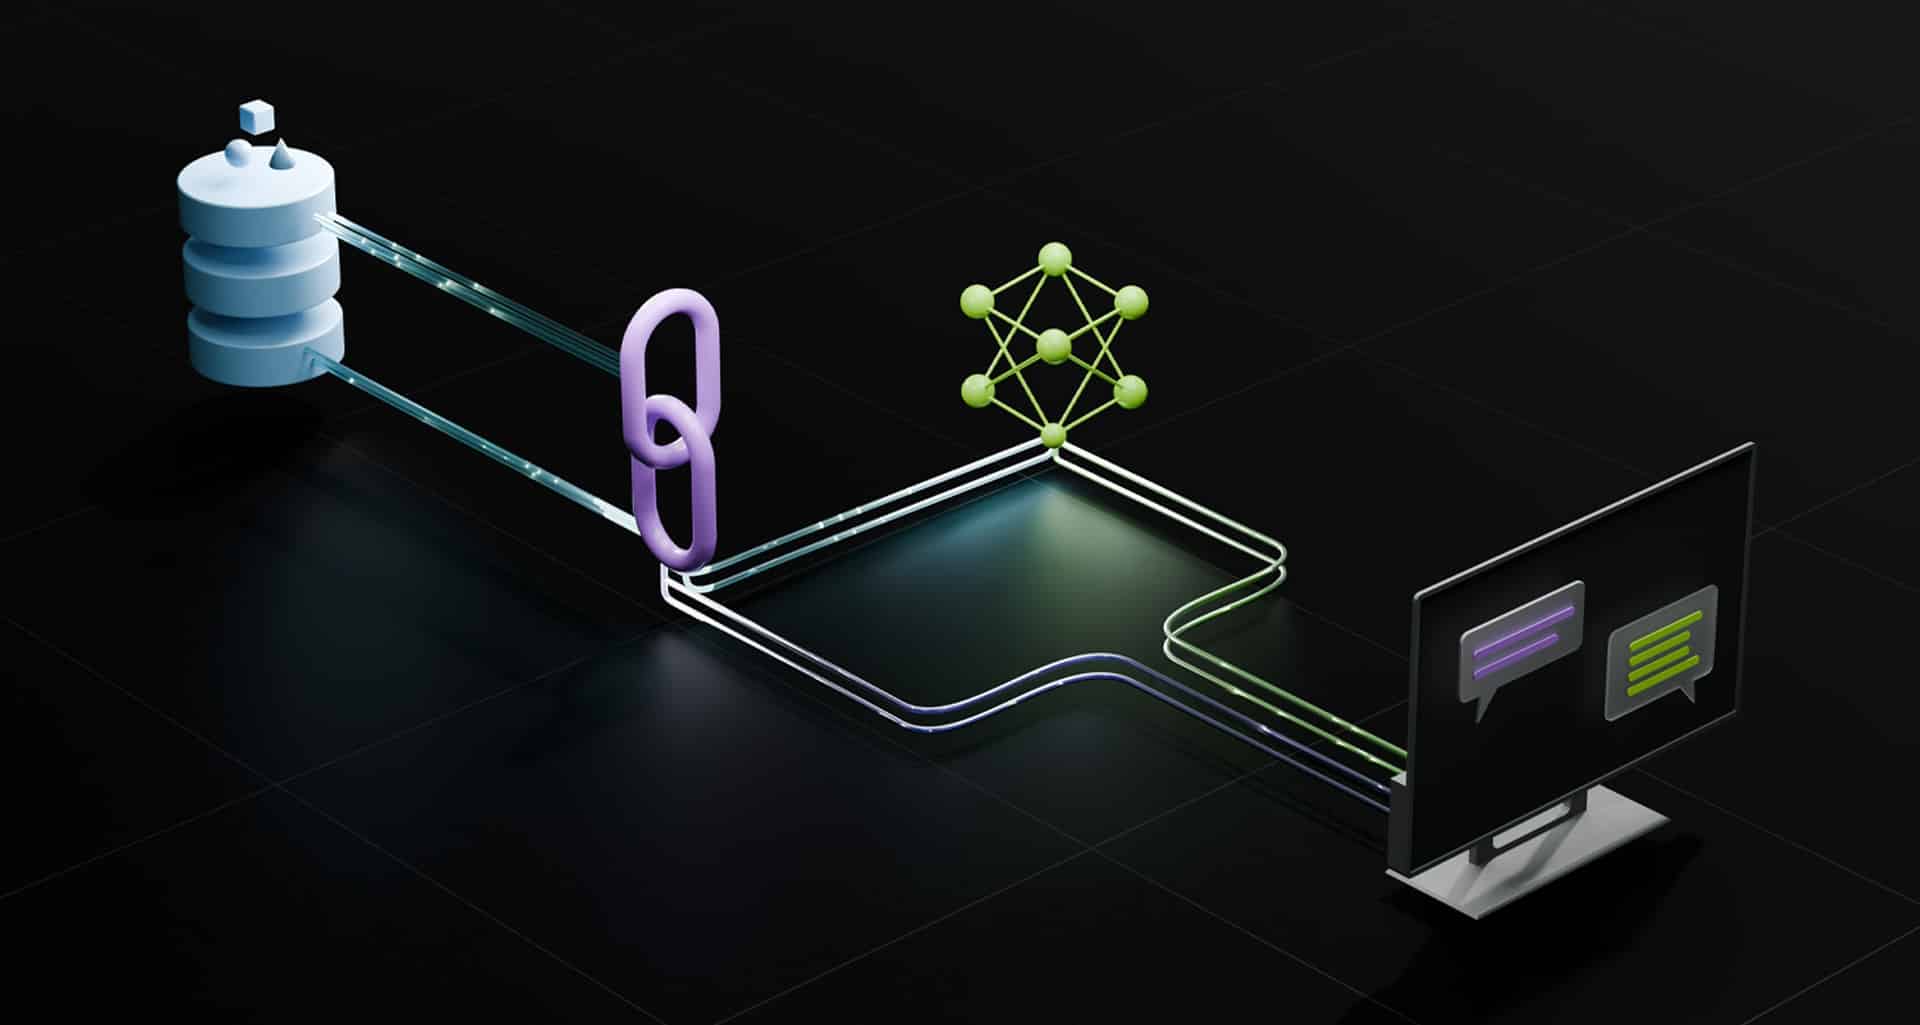
Before the AI answers, another part of the system searches for relevant information. It might look through policy documents, support articles, product manuals, meeting notes or database records. A few useful pieces are then placed in front of the language model, which writes its answer using that material.
So when you ask, “Can I expense airport Wi-Fi?”, the model doesn’t have to rely only on whatever it learned during training. It can check your organisation’s actual travel rules first. RAG combines retrieval with generation rather than expecting the model to carry every fact inside itself.
That’s the trick.
And honestly, it’s a good trick. Just not magic.
The chatbot is not learning your company
People hear that an AI can answer questions about private documents and assume the model has absorbed the whole company. It hasn’t.
In a typical RAG setup, the model isn’t retrained every time somebody uploads a handbook or edits a support page. The documents are prepared for search, and relevant parts are supplied when a question arrives.
Suppose finance updates the reimbursement limit on Monday. With a well-run RAG system, the new document can become searchable without rebuilding the underlying model. That is much quicker than teaching the model the company all over again.
Of course, somebody still has to remove the old document.
This is the part demos skip.
One folder called “Final” can ruin the afternoon
Most companies don’t have a knowledge problem. They have a document problem.
The same policy exists in SharePoint, somebody’s Google Drive and an email attachment from eleven months ago. One copy says “approved.” Another says “approved_final.” A third says “approved_final_v3_USE_THIS.”
Then a team connects an AI assistant to the whole mess and expects clarity.
A support team tests its new bot against product documentation. The bot gives the wrong price even though the correct figure is clearly written in the knowledge base. After some digging, the team finds three older pages containing the previous price. Nothing mysterious happened. The search system simply handed the model the wrong evidence.
RAG doesn’t clean your information. It reveals how dirty it already is.
Most failures are painfully ordinary
When a RAG assistant gives a bad answer, everyone looks at the language model because that’s the famous part.
Often, the failure happened earlier.
Maybe a long document was chopped into awkward pieces and the important sentence got separated from its heading. Maybe the user asked for “parental leave” while the policy uses “family care absence.” Maybe permissions were ignored. Maybe the correct result ranked fifth and only the first three were sent to the model.
Modern RAG pipelines often convert documents into searchable representations, retrieve relevant chunks and pass them into the model as context. The quality of retrieval has a direct effect on the answer.
If the system retrieves rubbish, the model becomes a very articulate rubbish processor.
Harsh, perhaps. Still useful, because it tells you where to look.
A source link is not decoration
I don’t trust an internal AI assistant that won’t show where its answer came from.
For low-stakes questions, perhaps it doesn’t matter. Ask where the office printer is and nobody needs a legal citation. Ask about a contract clause, security procedure, customer refund or employee benefit and the source becomes part of the answer.
A useful RAG tool should let you open the document, see the relevant passage and check its date. Some systems produce a clean response but attach a source that barely supports it. That’s not grounding. That’s a confidence accessory.
Here’s the thing. RAG can reduce guessing, but it doesn’t remove it. Retrieved text may be incomplete, conflicting or wrong. Research on retrieval-augmented systems has also shown that irrelevant passages can mislead the generator.
The human still has a job.
Where it earns its keep
RAG is most useful when people repeatedly search through a known body of information.
Customer support is an obvious case. Instead of memorising hundreds of product rules, an agent can ask a question and get an answer linked to the current article. Engineers can search runbooks while handling an incident. A sales team can query approved product material without digging through Slack messages from last quarter.
My favourite use is less glamorous: finding decisions.
Teams make choices during calls, write them in meeting notes, and then forget where those notes live. Six weeks later, someone starts the same discussion again. A decent retrieval system can surface the earlier decision, who made it and what assumptions were used.
That saves more time than another chatbot writing cheerful email drafts.
Don’t connect everything on day one
The common enterprise instinct is to feed the system every available document and announce that it now understands the organisation.
Usually a mistake.
Start with one collection that has a clear owner: support articles, HR policies or technical manuals. Remove duplicates. Mark outdated pages. Test real questions, including vague ones and questions with no answer. Check whether the system is willing to say it couldn’t find enough evidence.
Especially test that last part.
A RAG assistant that refuses occasionally is healthier than one that answers everything. People may complain that it feels less impressive. Good. Impressive is not the same as dependable.
The acronym will probably continue appearing in AI proposals and vendor presentations. That’s fine. Behind it is a sensible habit: look up the relevant information before speaking.
Most offices could use more of that, with or without AI.